The guide
The five levels of local AI, and what each machine unlocks
Every private AI machine runs the same software. What separates a $5,000 box from a $25,000 one is two numbers: how much memory it has, and how fast that memory is. Memory size decides how big a model fits and how many people can ask at once. Memory speed decides how fast the answer appears. Once you know those two numbers, the whole market is easy to read.
Below: the five levels we install, the machines that reach each one, what each upgrade actually buys you, and the limits we would rather tell you about now than after the cheque.
Memory size: what fits
A model has to sit entirely in the machine's AI memory to run well. A 30B-class model takes about 18–20 GB. A 120B mixture-of-experts model about 65 GB. A 400B-class model 200 GB or more. On top of the model you need room for the documents it is reading (a long contract is 30–60 thousand tokens) and a slice for every person asking at that moment. Rule of thumb: model + 2 GB per simultaneous user + the search index.
Memory speed: how fast it answers
Each word the model writes means reading the whole active model out of memory once. So words per second is roughly memory speed divided by active model size. A dense 70B model (about 40 GB active) on a 273 GB/s Spark: 4–6 words a second, slower than you read. The same model on a 1.2 TB/s Mac Studio Ultra: about 25. A 30B model on the Apex's 1,792 GB/s: faster than anyone can read, for five people at once.
The five levels
A Spectre tower Level 1
Solo
One person: a developer, analyst or owner who wants a private assistant on their own machine.
- People at once
- 1
- Model class
- 7–20B models, or a 27–30B model squeezed in at low precision
- Examples
- gpt-oss-20b, Qwen 3.5 27B (4-bit), Gemma 4 E4B
Unlocks
- Private chat and drafting
- Code help
- Summaries of documents you drop in
Limits
- One person at a time
- A 16 GB card runs out of room when a long document and a capable model are both loaded
- Not enough for a shared library
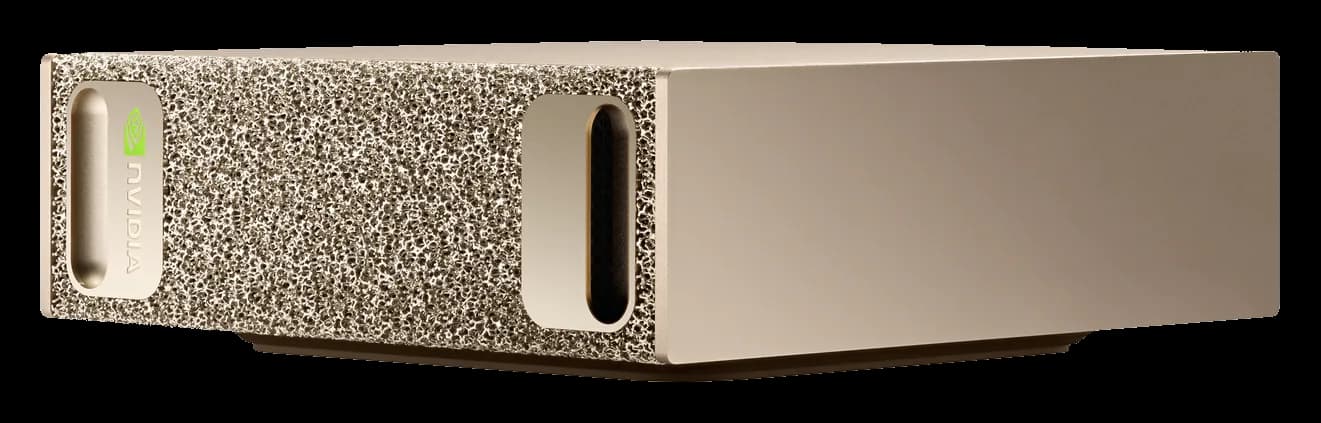
NVIDIA DGX Spark Level 2
Team
2–10 staff who want one private assistant that knows their documents.
- People at once
- 5 at once
- Model class
- 27–32B models fully in memory
- Examples
- Gemma 4 31B, Qwen 3.5 27B, gpt-oss-20b
Unlocks
- A shared document library: ask a question, get the answer with the file it came from
- Drafting letters, emails and summaries from your own records
- Everyone gets an account; nothing anyone types leaves the room
Limits
- Long, many-step reasoning is weaker than the 120B models one level up
- About ten people before answers start to queue
Machines: NVIDIA DGX Spark, 64 GB ($4,999) · Apple Mac Studio, M5 Max, 128 GB ($4,799) · Spectre Apex (RTX 5090, 32 GB) ($9,999)
Team Install: $2,500, optional Team Support $250 a month
NVIDIA DGX Spark on an office desk Level 3
Office
10–40 staff, or an office whose work is long documents: contracts, records, filings.
- People at once
- 10–25 at once
- Model class
- 100–120B mixture-of-experts models
- Examples
- gpt-oss-120b, Qwen 3.x Flash-Next, GLM-5.3-Flash
Unlocks
- Noticeably better reasoning: multi-step questions, comparisons across documents
- Whole contracts and long email threads in one question
- Reading scans and images (OCR and vision)
- Department workspaces with separate document sets
Limits
- Dense 70B-class models fit but answer slowly on a Spark or Max; the 120B mixture models are the right choice here
- Still behind the best cloud models on long autonomous tasks
Machines: NVIDIA DGX Spark, 128 GB ($6,950) · Apple Mac Studio, M5 Ultra, 96 GB ($5,499) · NVIDIA DGX Spark, 64 GB ($4,999)
Office Install: $4,500, optional Office Support $450 a month
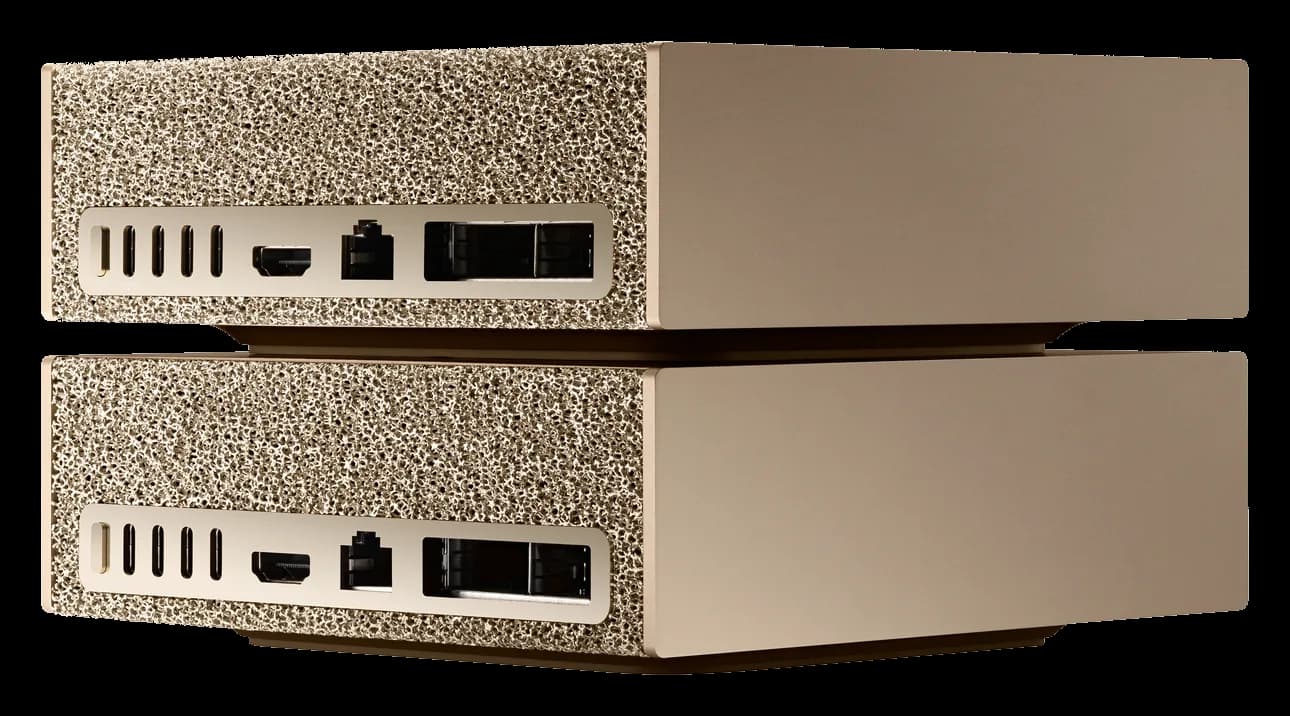
Two NVIDIA DGX Spark, joined Level 4
Company
40+ staff, several departments, or work that needs the biggest open models.
- People at once
- 25–60 at once
- Model class
- 200–400B mixture-of-experts models; 70B-class models at full speed
- Examples
- Qwen 3.x 235B, GLM-5.x, DeepSeek V4 Flash, Llama 70B-class
Unlocks
- Frontier-class open models: the closest you can get to the big cloud models without the cloud
- Several models running at once: one for documents, one for code, one for images
- Company-wide use with headroom
Limits
- Two boxes or a top-spec Mac: more to install and more to keep updated
- 100+ heavy users need Level 5
Machines: Apple Mac Studio, M5 Ultra, 256 GB ($9,499) · Two NVIDIA DGX Spark 128 GB, joined ($13,900) · Spectre Apex Pro (RTX PRO 6000, 96 GB) ($23,499)
Company Install: $7,500, optional Company Support $750 a month
NVIDIA DGX Station Level 5
Enterprise
IT-run organisations with 100+ users, or anyone who needs to fine-tune models on their own data.
- People at once
- 100+
- Model class
- Any open-weight model, served to many users
- Examples
- Anything above, at full precision, Fine-tuned models trained on your data
Unlocks
- Many simultaneous users with fast answers
- Fine-tuning
- Several locations
Limits
- Server hardware from about $95,000; quoted case by case with your IT team
Every machine we install, side by side
Prices are the makers' published prices, checked October 5, 2026. Speeds are approximate single-user figures measured by us and by the community; they vary with model, precision and settings.
| Machine | Memory | Speed | List price | Typical speeds | Best for |
|---|---|---|---|---|---|
| NVIDIA DGX Spark, 64 GB | 64 GB | 273 GB/s | $4,999 | Gemma 4 31B ≈ 9–12 tok/s; gpt-oss-20b ≈ 45 tok/s | The lowest-cost team machine: a 30B-class model fully in memory with room for ten people's documents. |
| NVIDIA DGX Spark, 128 GB | 128 GB | 273 GB/s | $6,950 | gpt-oss-120b ≈ 60 tok/s (≈ 40 with a long document) | The Office-level machine: runs the 120B-class open models that reason noticeably better than 30B ones. |
| Two NVIDIA DGX Spark 128 GB, joined | 256 GB | 273 GB/s | $13,900 | GLM-5.3-Flash (300B-class) ≈ 33 tok/s | Frontier-class open models for a whole company, on two quiet boxes. |
| Apple Mac Studio, M5 Max, 128 GB | 128 GB | 614 GB/s | $4,799 | 100B-class MoE ≈ 40–60 tok/s | A team that already runs on Macs: twice the memory speed of a Spark, 128 GB, silent. |
| Apple Mac Studio, M5 Ultra, 96 GB | 96 GB | 1.2 TB/s | $5,499 | gpt-oss-120b ≈ 100+ tok/s; 70B dense ≈ 25 tok/s | The fastest answers under $6,000: 1.2 TB/s memory, 96 GB, silent. |
| Apple Mac Studio, M5 Ultra, 256 GB | 256 GB | 1.2 TB/s | $9,499 | 100B-class MoE 100+ tok/s; 400B-class ≈ 20–30 tok/s | Frontier-class open models in one silent box, with the fastest memory you can buy on a desk. |
| Spectre Apex (RTX 5090, 32 GB)built here | 32 GB | 1.8 TB/s | $9,999 | 32B-class ≈ 60–75 tok/s; 8B ≈ 200+ tok/s | The fastest team machine: a 30B-class model answering five people at once with no waiting. |
| Spectre Apex Pro (RTX PRO 6000, 96 GB)built here | 96 GB | 1.8 TB/s | $23,499 | 70B dense ≈ 30 tok/s; gpt-oss-120b ≈ 80+ tok/s | 70B-class models at full precision and 120B models at speed, on one workstation card built for 24/7 use. |
What each upgrade actually buys you
16 GB (a developer tower) → 32 GB (Spectre Apex)
The first level where a 30B-class model sits fully in memory with room for five people's documents. Below 32 GB the model is squeezed and a shared library does not fit. This is the entry point for a team, and the Apex does it at six times a Spark's memory speed.
32 GB → 64 GB (DGX Spark 64)
The same 30B-class models at more comfortable precision, twice the room for documents and people, and the first 100B-class mixture-of-experts models become possible (tight). What you give up against the Apex is speed: 273 GB/s against 1,792.
64 GB → 128 GB (DGX Spark 128, Mac Studio M5 Max)
The step most offices feel. The 100–120B mixture-of-experts models (gpt-oss-120b and its peers) load fully and reason noticeably better than 30B models: multi-step questions, comparisons across documents, whole contracts in one go, OCR and vision. Ten to twenty-five people at once.
128 GB at 273 GB/s → 96–256 GB at 1.2 TB/s (Mac Studio M5 Ultra)
Speed, not just size. Four times the memory bandwidth means long answers arrive four times faster, and dense 70B-class models become usable (about 25 tok/s instead of 4). The 256 GB version adds the 200–400B frontier-class open models.
128 GB → 256 GB (two Sparks joined, or the 256 GB Mac Studio)
Frontier-class open models: the biggest things you can run without a data centre. Several models at once (documents, code, images). A company of 25–60 people asking at once, with headroom. Two Sparks also mean one can update while the other answers.
A desk machine → A server (DGX Station, multi-GPU)
Many simultaneous users with fast answers, fine-tuning on your own data, several locations. From about $95,000. We quote it with your IT team rather than list it.
Three things to know before you buy
- Local models trail the best cloud models on long, many-step autonomous work. They are excellent at the things an office actually asks: find, summarise, compare, draft, extract, and show me where it came from.
- Hardware prices move. NVIDIA raised the Spark's price twice in 2026 and Apple's 512 GB Mac Studio has no price yet. We sell at list, so your quote shows the maker's price on the day.
- Owning the machine does not make a firm compliant with anything by itself. It removes the outside AI vendor from the picture; your own policies and access controls still do the rest.
Questions about the levels
What is a 'B' and why does it matter?
+
B is billions of parameters, the size of the model. Bigger models know more and reason better. A 30B model needs about 18–20 GB of memory at the usual precision; a 120B mixture-of-experts model about 65 GB; a 400B-class model 200 GB or more. The memory has to hold the model, the documents it is reading, and one slice per person asking.
What is a mixture-of-experts model and why do you keep recommending them?
+
A model where only part of the network runs for each word. gpt-oss-120b has 120 billion parameters but uses about 5 billion per step, so it reasons like a big model and answers at the speed of a small one. On unified-memory machines like the Spark and the Mac, that is the trick that makes big models usable. Dense models (every parameter every step) need fast memory to be quick, which is why 70B dense is slow on a Spark and fine on a Mac Studio Ultra or an Apex Pro.
What does 'tokens a second' mean to me?
+
Roughly words a second. People read at about 4 to 5 words a second, so anything above 15 tokens a second feels instant for one person. Divide by the number of people asking at the same moment.
Why not just buy the biggest machine?
+
Because for most offices a 30B or 120B model answers the real questions (what does this contract say, draft this reply, find every file about this client) and the money is better spent on a faster machine or on the install. We will tell you when a bigger model would actually change the answers you get.
Are these speeds guaranteed?
+
No. They are approximate figures measured by us and by the community on specific models and settings, and they change with model, precision, document length and how many people are asking. The Office and Company installs include a written speed test on your own machine with your own documents.
Not sure which level you are?
One consultation usually settles it: how many people, what documents, what you want it to do.